Products and Services
Fast Compression Backup and Archiving End-to-End Compression Data Analysis Data Acquisition Consulting
Company
Company Jobs
Downloads & Contact
Downloads Contact
Legal
Imprint Privacy Policy

Products and services

Compression, analysis and acquisition

NC16FC · Tuna & Dolphin

High-Speed Lossless Compression

Archiving and Backup

Overview

The ncfc archiving and backup tool is a command-line application for efficient and secure storage of sensor data on disk or in the cloud. It combines high compression speed with high compression ratio, achieving 30–60% reduction in storage footprint at a 100 MB/s per thread.

The compressor works on any type of data, and it performs exceptionally well on raw sensor data (e.g. camera images, radar data, detector data). It does not require any knowledge about the data, so you can use it like tar or zip to compress your data. This makes it ideal for archiving large image datasets where every bit matters, such as medical imaging, satellite imagery, and automotive camera data.

To estimate resources and costs for a complete data pipeline, use our Resource and Cost Calculator.

Features

ncfc supports local drives, NAS, and a wide range of cloud backends (AWS S3, Azure Blob Storage, Google Cloud Storage, SFTP), providing maximum flexibility and avoiding vendor lock-in.

Security is built in using XChaCha20-Poly1305 authenticated encryption (AEAD): data can be encrypted before it leaves your system, ensuring confidentiality and integrity. Encryption can easily be enabled on a per-file basis by passing the -x flag when adding files to an archive. The master key is protected with a passphrase and stored locally, and the encryption daemon (ncfc daemon) holds the key in memory so the passphrase needs to be entered only once per session (similar to ssh-agent).

Built-in indexing, chunking, versioning and tagging enable instant search and point-in-time recovery. Data is bundled into large chunks, reducing cloud storage objects and lowering metadata and retrieval costs. Archives are append-only, making accidental deletion of files in the archive impossible. Files are automatically versioned; when updated, a new version is created while the original remains in the archive. If the network connection drops or the process is interrupted during an upload, the archive stays consistent and the operation can be resumed later.

ncfc follows a subcommand-based interface:

ncfc <archive_url> add/get/list [options]

The archive URL determines the backend: s3://, az://, gs://, sftp://, or local path.

Examples:

  • ncfc /storage/2026_projectA.ncfc add -i /ssd/data -cl 1
    add everything in /ssd/data to /storage/2026_projectXYZ.ncfc and compress at level 1 (fast)
  • ncfc s3://bucket/2026_projectA.ncfc add -i /ssd/data -cl 2
    add everything in /ssd/data to an archive in an AWS S3 bucket, compressed at level 2 (best)
  • ncfc s3://bucket/2026_projectA.ncfc get -i "**.raw" -e "test/" -e "**2026*" -o /tmp/rawdata
    extract all raw files recursively from an archive in an AWS S3 bucket to /tmp/rawdata, excluding the test/ directory and files that contain the string '2026'

System requirements: Linux 64-bit, AVX2 support, 150 MB RAM per worker thread. Download the ncfc manual, and contact us for custom solutions.

To estimate the resources and costs for a complete data pipeline, use our Resource and Cost Calculator.

End-to-End Data Compression Solutions

Overview

Modern data acquisition systems — whether in automotive testing, industrial monitoring, or scientific research — generate massive amounts of sensor and camera data. An efficient data pipeline typically spans three stages: high-speed recording, data transfer, and central storage.

nanocode provides fast real-time compression directly on the edge device with nc16fc, ensuring high-speed data reduction at up to 3 GB/s per CPU core during recording. For long-term storage, our ncfc tool offers on-premise or cloud-based archiving with maximum compression ratio and encryption, reducing costs and keeping the data secure.

Use the calculator below to estimate resources and costs for your specific data pipeline.

Fast Compression nc16fc

Double disk read/write speed with our high-speed lossless compression algorithms for CPU, GPU and FPGA. Perfect for on-the-fly compression inside a vehicle.

Backup and Archiving ncfc

Compress, encrypt and store your data safely on disk or in the cloud, with maximum compression ratio and 100 MB/s per thread.

Use Case: Data Acquisition, Upload, and Cloud Storage in the Automotive Industry

In large-scale automotive data collection, test fleets are equipped to record massive amounts of sensor and camera data. The calculator below helps you estimate the complete cost and resource requirements for your data pipeline from vehicle to cloud.

  1. In-Vehicle Recording: Vehicles collect data continuously using onboard data recorders and computing systems. The choice of compression algorithm affects CPU requirements, storage capacity, and how often data must be transported to upload stations. A vehicle typically contains one data recorder but may include multiple compute servers for real-time processing.
  2. Upload Station: At the upload station, data from vehicles is prepared for cloud storage. If data arrives pre-compressed with one algorithm but needs to be stored with another for optimal cloud costs, it must be decompressed and recompressed, which requires additional CPU resources.
  3. Cloud Storage: The final stage involves storing compressed data in the cloud and accessing it as needed. Costs include storage fees, data transfer (upload/download), API requests, and compute resources for decompression during reads.

Hover over input field labels in the calculator to see detailed explanations of each parameter.

Resource and Cost Calculator

Number of Vehicles
Data Rate per VehicleMB/s
Total Data to RecordTB
Data Transport Cost per Trip€
Recording duration per triph
Compute Cost€/core
Storage Cost€/TB

Results

No compressionnc16fc
Required write speed——
Required CPU cores——
Transports to data centre——
Recording duration per trip——
Transport cost——
Project duration——
Total cost——
Total Data to UploadTB
CPU Cores Availablecores
Upload BandwidthMB/s

Results

No compressionnc16fc
Effective upload speed——
Upload time——
Required CPU cores——
Total cost——
Data VolumeTB
Storage Durationmonths
Number of Downloads
Number of Dataset Reads
Storage Cost per month€/TB
Download Cost€/TB
Read Cost€/TB

Results

No compressionncfc
Stored data——
Storage cost——
Download cost——
Read cost——
Total cost——

CPU core requirements are estimated as one core per 1 GB/s of disk write throughput (compressed or uncompressed), plus the cores needed for compression itself based on each compressor's per-core compression speed.

All values are approximate. Costs for energy, personnel etc. are not included.
For precise results, please contact us and provide representative sample data — we will analyze it and provide realistic estimates of compression ratio and speed for your use case.

Data Analysis

Overview

Modern industrial and scientific systems generate massive data volumes that require efficient processing to reveal the underlying signal. We specialize in the acquisition, analysis, visualization, and interpretation of complex sensor data, covering the entire workflow from calibration and filtering to statistical analysis, noise reduction, and signal extraction. Our custom algorithms and highly optimized implementations enable real-time processing even for demanding high-throughput applications.

Analysis Modules

Our data analysis toolkit includes optimized modules for the complete signal processing pipeline. Each module is designed for maximum throughput and can be deployed on CPU, GPU, or FPGA depending on your performance requirements.

  • Signal Processing:
    Fast and efficient algorithms for noise reduction, filtering, deconvolution, and baseline estimation isolate relevant features from raw sensor data.
  • Time Series Analysis:

    Event filtering and time-series analysis modules process temporal data streams, extracting trends, correlations, and significant changes over time.

  • Big Data Analysis:

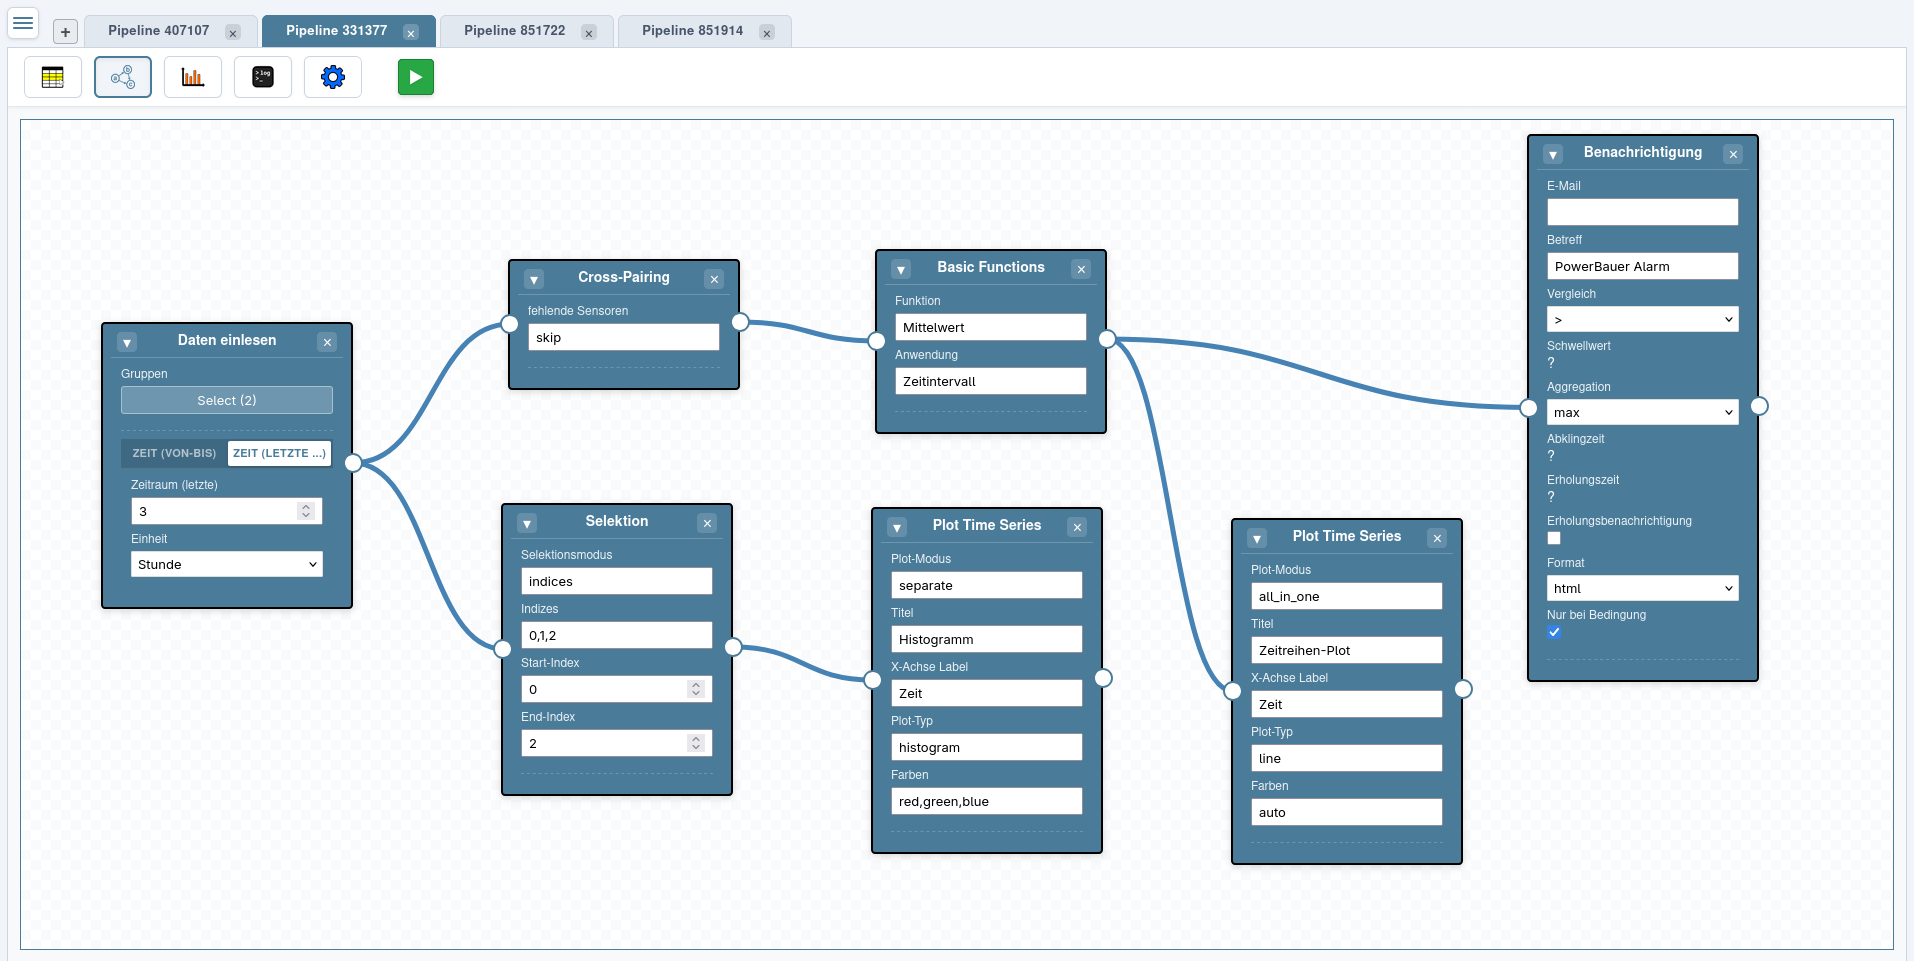
    For large sensor networks, a centralized on-site database stores all measurement data, ensuring full user access and control over the complete dataset. A browser-based graphical interface enables users to build analysis pipelines via drag-and-drop, combining multiple visualization types, outlier detection, and configurable alert notifications into flexible workflows.

  • Computer Vision:
    Real-time object detection, recognition and tracking modules process video streams with low latency. Sensor fusion algorithms combine data from multiple sensors to improve accuracy.
  • Machine Learning:
    Classification and regression modules apply trained models to streaming data, while clustering algorithms reveal patterns in high-dimensional datasets. Anomaly detection identifies unusual events for further investigation.

Example: Real-Time Baseline Estimation

In many real-time scenarios, the current data sample must be calibrated and analyzed on the fly, often without knowing the next sample. In order to estimate the baseline of a time series, the algorithm must decide whether a new sample is noise, signal, a jump in the baseline, or part of a trend.

In this example, raw data from a photomultiplier tube are combined with an artificial function to illustrate how the algorithm deals with jumps and trends.

Example: Flexible Analysis Pipelines

A browser-based graphical interface enables users to build analysis pipelines via drag-and-drop, combining multiple visualization types, outlier detection, and configurable alert notifications into flexible workflows.

Flexible Analysis Pipelines
Data Acquisition

Overview

A highly efficient Ethernet protocol and interfaces allowing data recording at highest rates.

Our Ethernet-based data acquisition solutions using our custom EFBP protocols provide:

  • Extremely high throughput (up to 3 GB/s per CPU core), comparable to or better than most custom hardware solutions
  • High degree of scalability
  • Low cost through the use of standard communications hardware

The technology has been implemented in the FlashCam and Legend projects.

We cover everything: sensors, triggers, timing, electronics, transmission, FPGA, server, software. In this example, nanocode's technologies are combined with a PXI Logger by Konrad GmbH.

Transient Recording

For many applications, disk I/O rates and disk capacity limit the rate at which data can be acquired and processed.

Transient digitizers record waveforms at high sampling rates, often for many channels in parallel, generating a significant data stream. Records need to be time-tagged and synchronized.

nanocode's high speed, high volume data transfer techniques such as the EFBP Ethernet protocol are ideal to harvest data from arrays of transient digitizers. Software techniques allow synchronization of digitizer channels at the micro-second level; hardware solutions can provide synchronisation at sub-nanosecond level.

The FlashCam camera recording sky images with 2000 digitizer channels at 250 Msamples per second uses the EFBP protocol for internal and external data transmission.

FlashCam

FlashCam is mounted in the focus of a huge 600 m² mirror and each second takes 250 million images of the sky over Namibia, searching for light flashes induced by cosmic particles.

Using Ethernet technology developed by nanocode's Thomas Kihm and the Max Planck Institute for Nuclear Physics, data are moved between the front-end digitizers and FPGA processors at a rate of several TeraBytes/s.

FlashCam Telescope
Consulting

System Architecture Consulting

Designing an efficient data acquisition or analysis system requires balancing multiple constraints: throughput requirements, latency limits, budget, and future scalability. We help you navigate these trade-offs and design a system architecture that meets your needs.

Our consulting covers the complete data pipeline: sensor selection and configuration, data acquisition hardware, network infrastructure, storage systems, and analysis software. We evaluate different technology options and recommend solutions based on your specific requirements.

Technology Evaluation

Uncertain whether your planned approach will work at the required scale? We can prototype critical components, benchmark different technologies, and provide data-driven recommendations before you commit to a full implementation.

This includes evaluating compression algorithms for your data type, testing network protocols for your throughput requirements, and assessing whether real-time processing is feasible with your computational budget.

Integration Support

Integrating new data acquisition or analysis capabilities into existing systems presents unique challenges. We assist with interface design, protocol adaptation, and ensuring compatibility with your current infrastructure while minimizing disruption to ongoing operations.

Code Optimization

Performance Optimization

You have developed an algorithm that solves your problem, but it's not running fast enough for production use? An external perspective often reveals optimization opportunities that are difficult to see from within a project.

We analyze your code to identify bottlenecks, improve algorithmic complexity, and exploit hardware-specific features. Our optimization work spans the full spectrum of computing architectures: multi-core CPUs with SIMD instructions (AVX, AVX2, AVX-512), GPUs for parallel processing, ARM processors (using NEON or SVE) for embedded systems, and FPGAs for custom hardware acceleration.

Data Structure Design

When I/O becomes the bottleneck, the solution often lies in better data organization. We design file formats and data structures optimized for your specific access patterns, enabling faster data retrieval and reduced memory footprint.

Our approach considers cache efficiency, memory alignment, compression integration, and parallel access requirements. The result: data structures that minimize latency and maximize throughput for your application.

Algorithm Development

Sometimes optimization requires rethinking the algorithm itself. We work with you to develop alternative approaches that achieve the same results with better computational efficiency, whether through mathematical reformulation, approximation methods, or hybrid algorithms that balance accuracy and speed.

Company

nanocode GmbH was founded in 2022 as a spin-off of the Max-Planck-Institut für Kernphysik (Max Planck Institute for Nuclear Physics) in Heidelberg, Germany. The company emerged from over a decade of research into high-throughput data systems used in particle and nuclear physics experiments, where raw data rates of tens of gigabytes per second are routine.

We transfer this deep expertise to the automotive industry and beyond, delivering production-ready software for data compression, data acquisition, and data analysis at the highest performance levels.

assembles long-term state-of-the-art experience in:

  • High-Speed Data Compression
  • Efficient Analysis of Complex Data Sets
  • High-Performance Data Acquisition Systems
  • Implementation of Algorithms in Software or Hardware (FPGA)

Our goal is to provide compact, low-footprint implementations of algorithms to efficiently manage and analyze your data. Contact us with your challenge — we look forward to hearing from you.

Downloads

Data Compression

Backup and Archiving

  • ncfc Manual — User manual for the ncfc archiving and backup tool
Contact

We are happy to hear about your project, your data, and your challenges. Whether you are looking for a compression library, a data acquisition system, custom algorithm development, or just an initial consultation — reach out and we will get back to you promptly.

You can also reach us directly by phone or email:

📞 +49 6226 7876840
✉ info@nanocode.com

Fill in the form below and we will respond within one business day.

Security Check

Jobs

We are constantly on the lookout for elite low-level developers who share our passion for fast, efficient software. If you excel in C, C++, Zig, or similar systems languages—and have experience with SIMD (AVX2, AVX-512), CUDA, or other performance-critical technologies—we would like to hear from you.

This is not a formal job posting. We welcome initiative applications at any time. If you are a strong programmer who cares about correctness, performance, and clean code, please reach out. We value talent and dedication over formal credentials.

Contact us with a short introduction and what you are interested in. We look forward to hearing from you.

×